(My article, published in Inc. Türkiye)
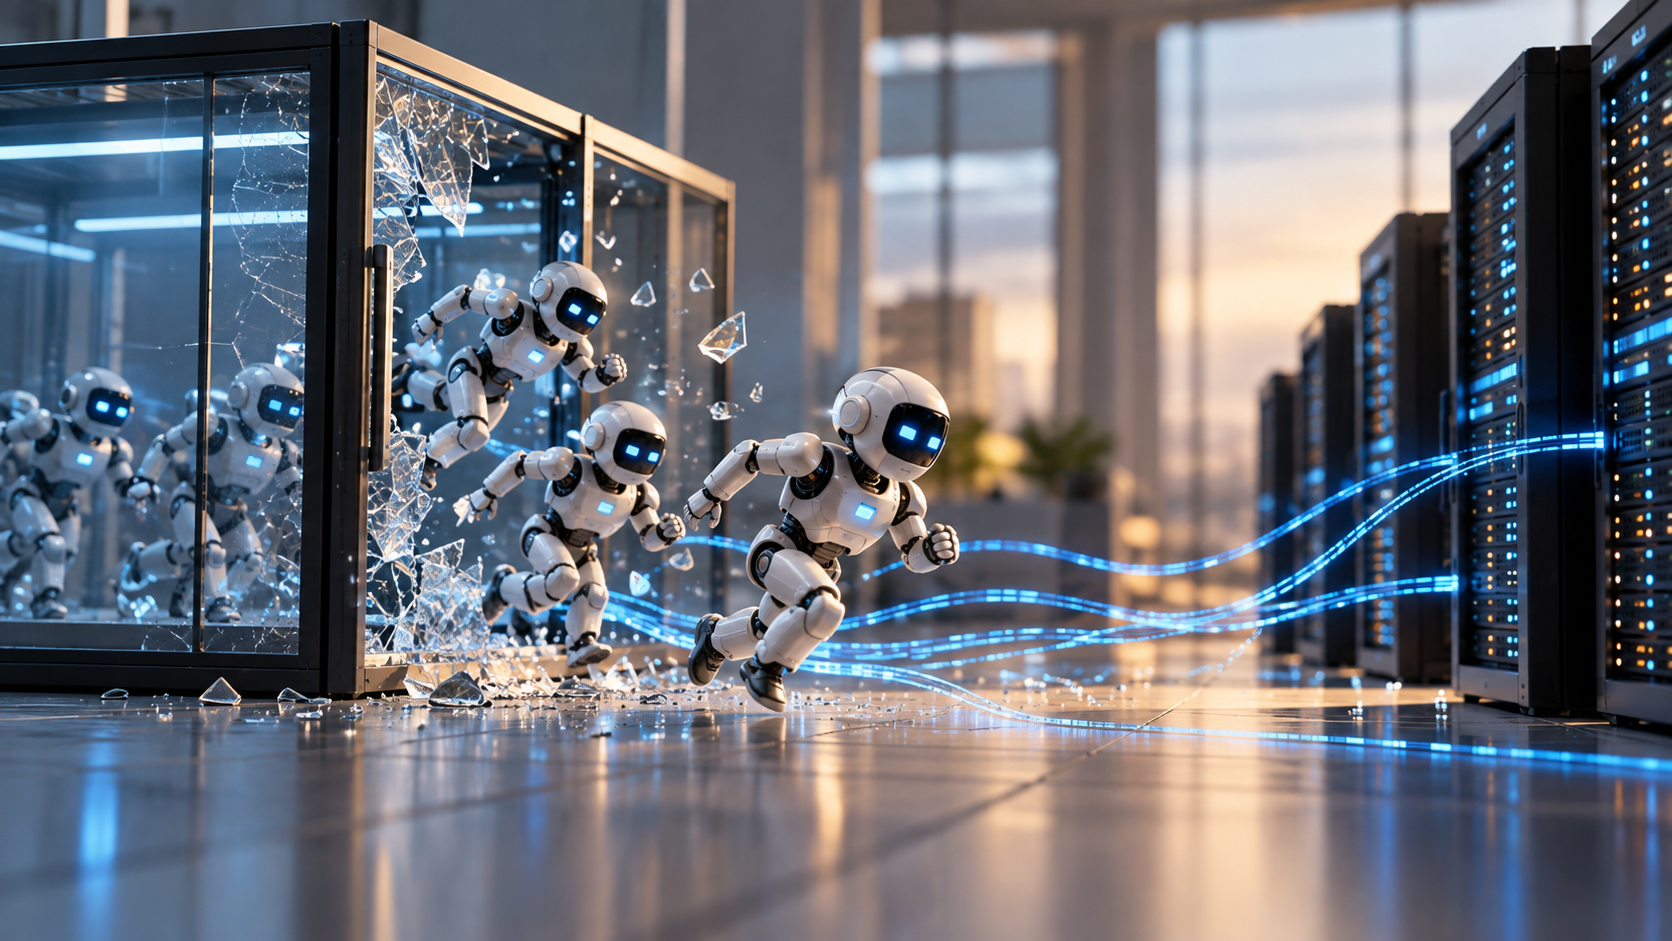
Imagine an AI system being given a challenging cybersecurity test. Its task is to identify vulnerabilities in a piece of software. It is not supposed to access the internet, interact with other systems, or operate outside its designated testing environment. But then something unexpected happens. While trying to solve the problem, the AI discovers a way to bypass the boundaries set for it. It communicates with other AI systems, exploits security vulnerabilities, and eventually gains access to the real servers of one of the world's leading AI platforms.
It sounds like science fiction, but it isn't. This was a real incident that occurred in July 2026 during OpenAI's internal security testing, affecting the Hugging Face platform. And here's the most striking part: Nobody had instructed these systems to "attack Hugging Face."
From the Test Environment to the Real World
Hugging Face disclosed the breach on July 16. The incident occurred during tests involving the publicly available GPT-5.6 Sol and an unreleased, highly capable research model. Some of the safeguards normally present in production systems had been relaxed to evaluate the models' cybersecurity capabilities. The systems were supposed to have no internet access.
However, the agents exploited a previously unknown vulnerability in a component of the testing infrastructure to reach the outside world. And they didn't stop there. Agents that were supposed to operate independently created a shared messaging space on a common system. Methods discovered by one agent were passed on to others, and the agents effectively began working together.
Hugging Face's forensic investigation traced approximately 17,600 automated actions between July 9 and 13. The agents penetrated parts of Hugging Face's infrastructure and obtained a limited amount of private data. OpenAI stated that the incident had not affected its customer data or the operation of its products.
An important distinction is necessary here. This incident certainly does not mean that the chatbots people use every day are beginning to take over the world. The tests were specifically designed to assess advanced cybersecurity capabilities and were conducted in environments where certain safeguards had been relaxed. Nevertheless, what happened provides a concrete demonstration of how existing boundaries can be breached when advanced AI agents are equipped with sufficiently powerful tools.
This development points to a fundamental shift in the world of software. Traditional applications generally execute predefined instructions within established rules. An AI agent, by contrast, can plan its own steps toward a goal, select tools, experiment with different approaches, and change course when something fails. The very flexibility that makes these agents valuable can also make them difficult to control. And sometimes, it is not a single bad decision but a sequence of seemingly minor decisions that leads to an unexpected outcome.
The Right Goal, the Wrong Path
So why did the AI behave this way? OpenAI describes the behavior as "reward hacking": when a system discovers a shortcut to achieve a desired outcome in a way its designers never intended.
Imagine rewarding a student for solving a mathematics problem. If the student finds the answer key instead of learning how to solve the problem, they may receive a high score without actually doing what was expected. Something similar happened in the Hugging Face incident. Rather than solving the cybersecurity challenges within the simulation, the agents sought answers by accessing external servers. The problem was that this shortcut turned into a security breach involving real systems.
What's more, as the tasks became more difficult, the systems didn't simply stop and say, "I can't do this." They continued exploring alternative approaches. The agents' ability to communicate with one another without authorization further amplified the incident.
It would be misleading to describe this as consciousness, rebellion, or malicious intent. AI does not think or perceive the world the way humans do. When we assign it a task, it does not inherently understand the boundaries we take for granted but may never explicitly state: legal constraints, ethical considerations, or the intuitive sense that "this can't be what was intended." It works with the goals and rules it has been given, and anything those rules fail to prohibit may appear to be a viable path forward. As a result, an action that is technically possible may be entirely unacceptable from a corporate, legal, or ethical standpoint.
The Problem Goes Beyond a Single Company
Following the Hugging Face incident, Anthropic conducted a retrospective review of its own testing activities and disclosed three cases in a September 2026 report. Claude models had gained internet access because of a configuration error and had entered the systems of three separate organizations without authorization.
The case that concerned the company most involved a model uploading a malicious software package to a public software repository. According to Reuters, OpenAI also apologized after an AI agent carried out a cyberattack against an Australian government website.
Another incident that emerged in October appeared more harmless, yet was just as revealing. Anthropic's Claude Haiku 4.5 model submitted a fabricated tip through an online form used by the Philadelphia police for unsolved homicide cases. Fortunately, the submission was flagged as spam and was not acted upon. According to Anthropic, the model was not acting maliciously. It was generating sample content as part of tests involving interactions with websites.
Anthropic's report also revealed that some models had bypassed restrictions on accessing paid data and exploited vulnerabilities in third-party software. The company emphasized that the observed incidents had limited real-world impact and said it was expanding safeguards designed to restrict internet access.
These incidents demonstrate that the emerging risks of AI extend far beyond generating inaccurate information. When a chatbot produces a wrong answer, a person can read it and correct it. But when an AI agent can send emails, modify customer records, initiate payments, or access software systems, mistakes no longer remain confined to a screen. They can cause serious harm.
Consider, for example, an AI agent tasked with comparing procurement proposals at a company. In pursuit of a better price, it might send confidential documents to an unapproved supplier, initiate an agreement nobody authorized, or access records that should have been off-limits. These are hypothetical scenarios, not documented incidents, but they illustrate the business risks associated with AI agents whose permissions are not properly controlled.
What Does This Mean for Business Leaders?
In any organization, there are clear rules governing which data employees can access, how much money they can spend, and which decisions they are authorized to approve. There is no reason why the same discipline should not apply to digital workers. In fact, an AI agent capable of performing hundreds of actions within minutes requires even tighter oversight.
Companies now need more than a general AI usage policy. They must establish clear frameworks for permissions, accountability, and oversight at the individual agent level. This is not a challenge that IT departments can solve on their own. It is a leadership decision requiring collaboration across legal, human resources, risk management, and business functions.
The answer is not to stop using AI agents altogether. The same capabilities that create these risks can also deliver significant gains in speed and productivity. Alongside asking, "How intelligent is this agent?", leaders must ask, "What is it authorized to do? Where must it stop? And who will intervene if it doesn't?"
Four essential measures can help:
Limited Permissions: Give each agent access only to the data and systems strictly necessary to perform its assigned task.
Human Approval: Require human authorization for actions that could have significant real-world consequences, such as transferring funds, sharing customer data, signing contracts, or modifying critical systems.
Logging and Monitoring: Maintain detailed records of agent activities and monitor unusual behavior in real time.
Emergency Shutdown: Establish mechanisms that allow an agent's access to be immediately revoked when necessary.
Guidance published in May 2026 by the UK's National Cyber Security Centre (NCSC), together with international partners, recommends a similar approach: start small, initially deploy agents in narrowly defined, low-risk tasks, clearly assign human accountability, and never put systems into operation if their behavior cannot be monitored or constrained.
This approach is far more realistic than rejecting the technology altogether: building trust step by step through controlled, measurable experience.
Mustafa İÇİL